G-VLA
ECCV 2026 · 2026
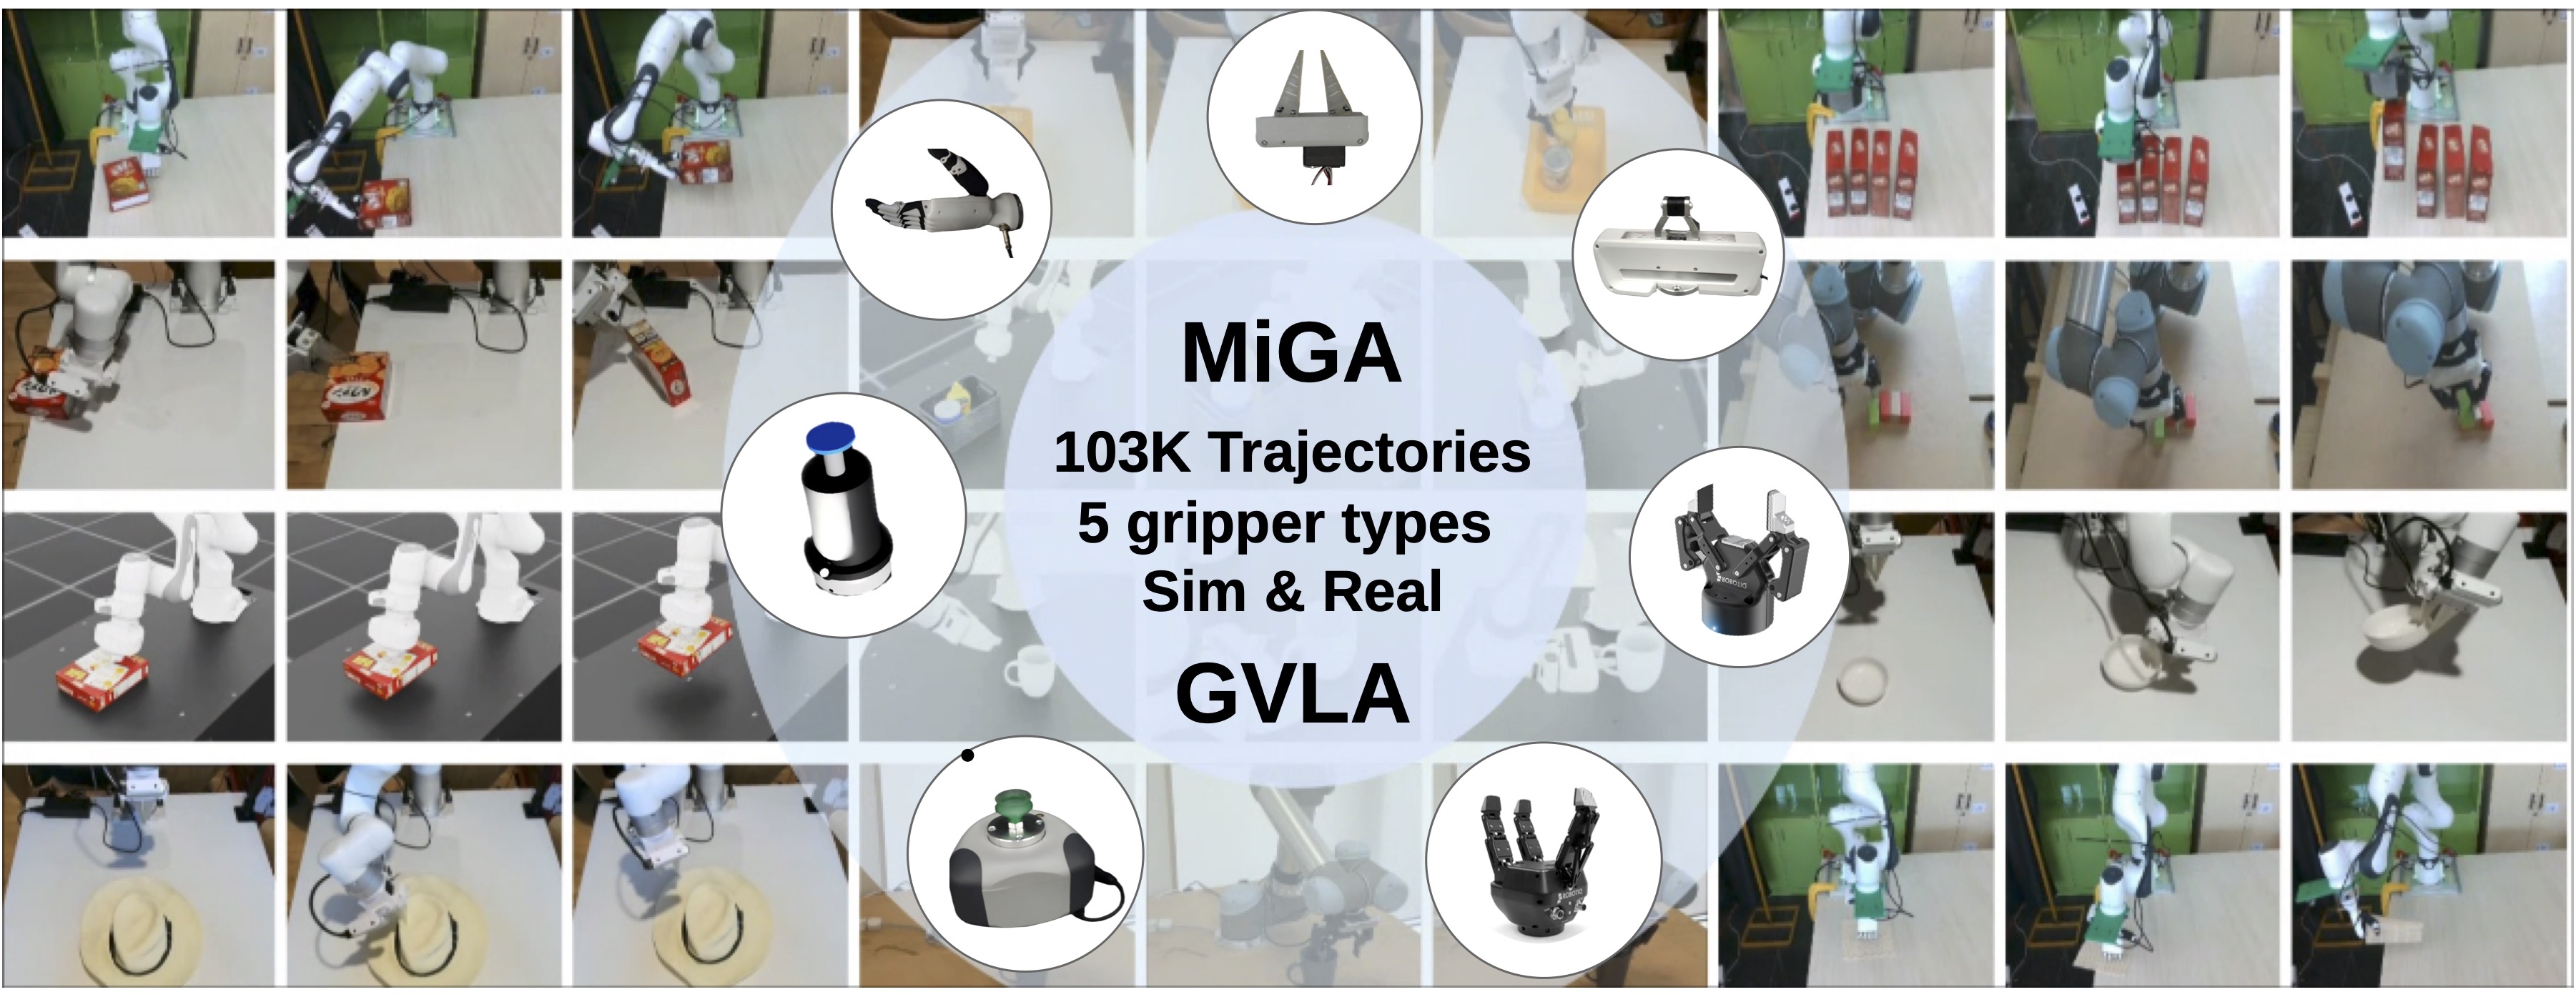
Gripper-aware Vision Language Action Models study how end-effector morphology should be incorporated into vision-language-action policies for more reliable and transferable robot control.
The work focuses on gripper-conditioned representations for manipulation and grasping, improving policy robustness across different hardware setups.
Paper: OpenReview · PDF
Publication
H. Zhang, Z. Luo, T. Li, K. Nguyen, B. Hela, S. Kumar, N. D. Tran, F. Dai, C. Munasinghe, J. P. Queralta, G. Toffetti, K. Vo, N. Le, R. Prakash, Q. Vuong, T. D. Ta, L. Hu, A. Nguyen, and B. Huang, “Gripper-aware Vision Language Action Models,” European Conference on Computer Vision (ECCV), 2026. OpenReview PDF.